When checking a new version of a site, you’ll probably open the homepage, a few important pages and whatever you’ve just changed. Meanwhile, crawlers are still requesting an old URL from three migrations ago and a page you’d completely forgotten existed. Conveniently, there’s a record of that.
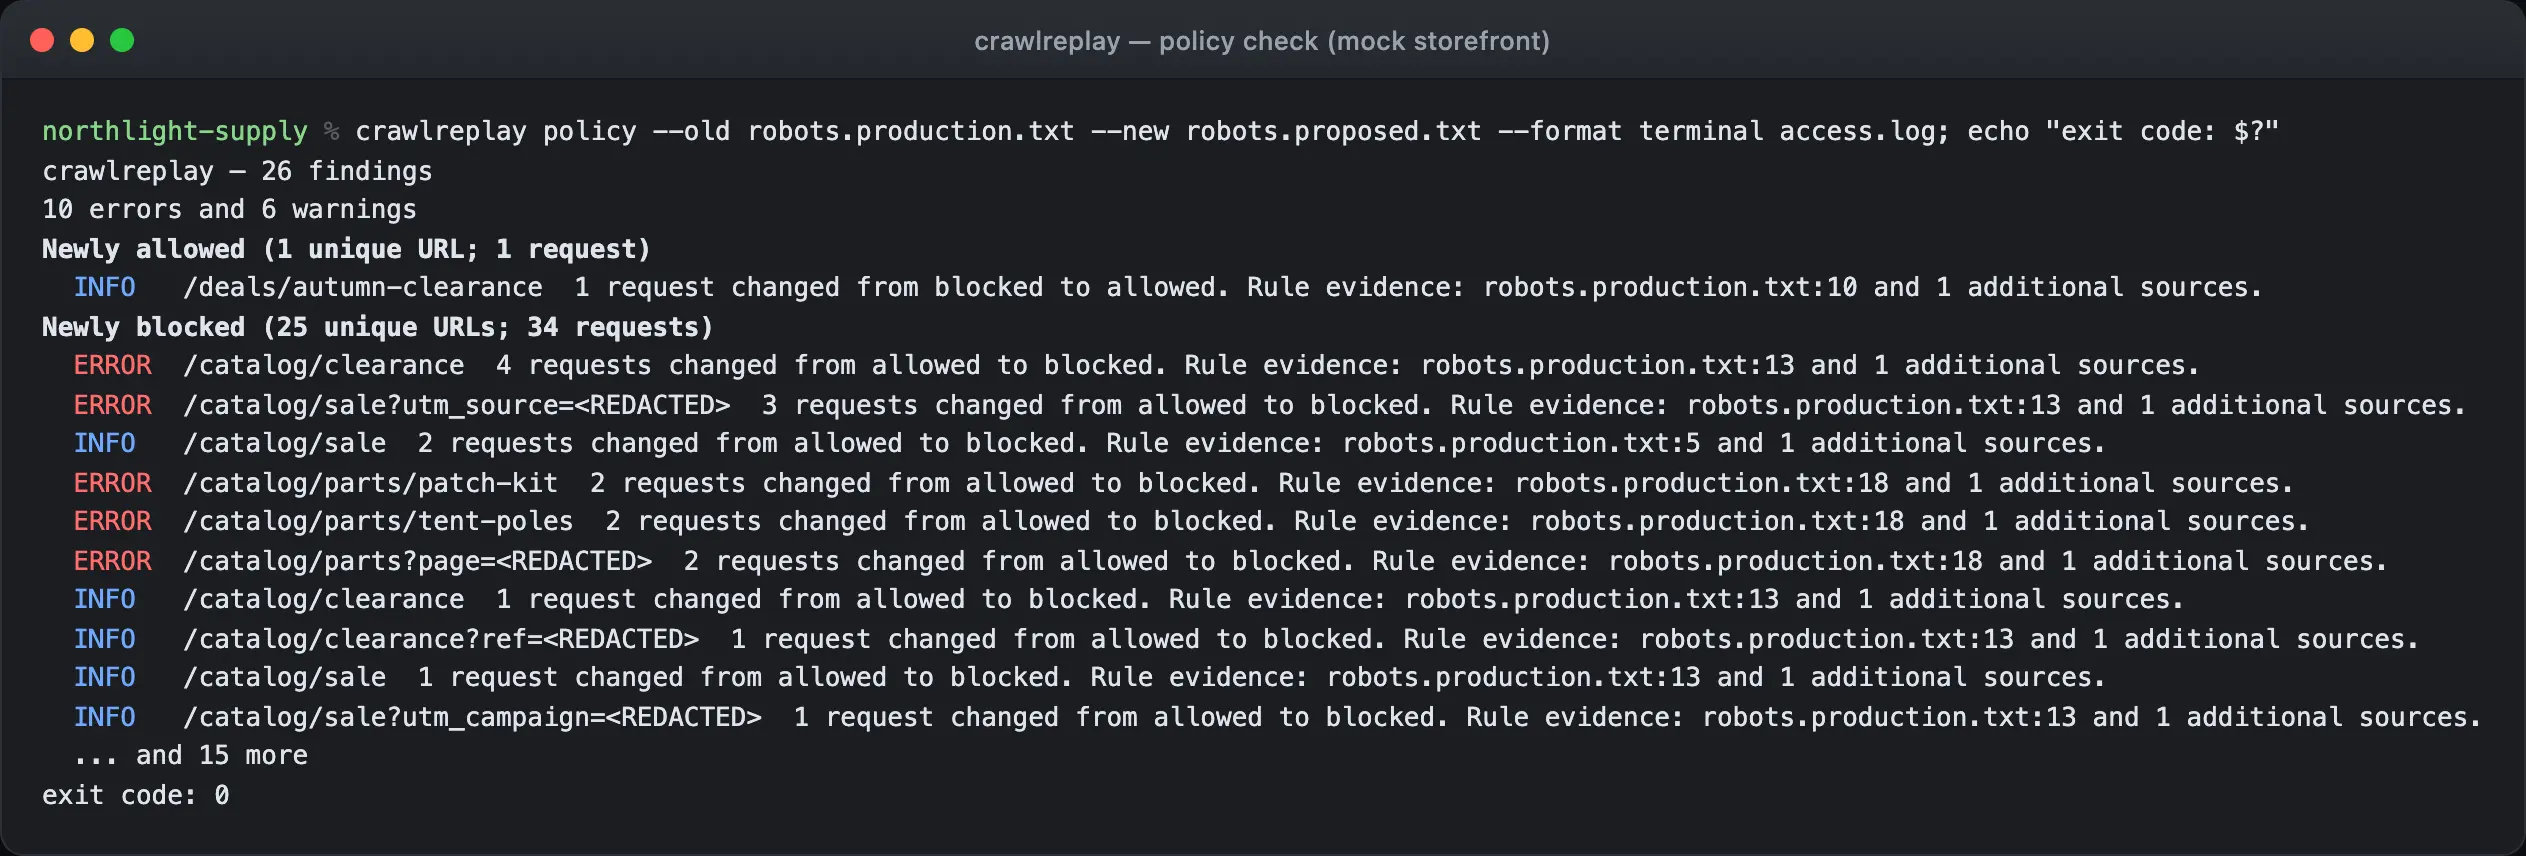
CrawlReplay uses those logs as the starting point. Give it your current and proposed robots.txt files, and it shows which logged crawler requests would become blocked or allowed under the new rules. Handy when a small cleanup turns out to cover rather more URLs than intended.
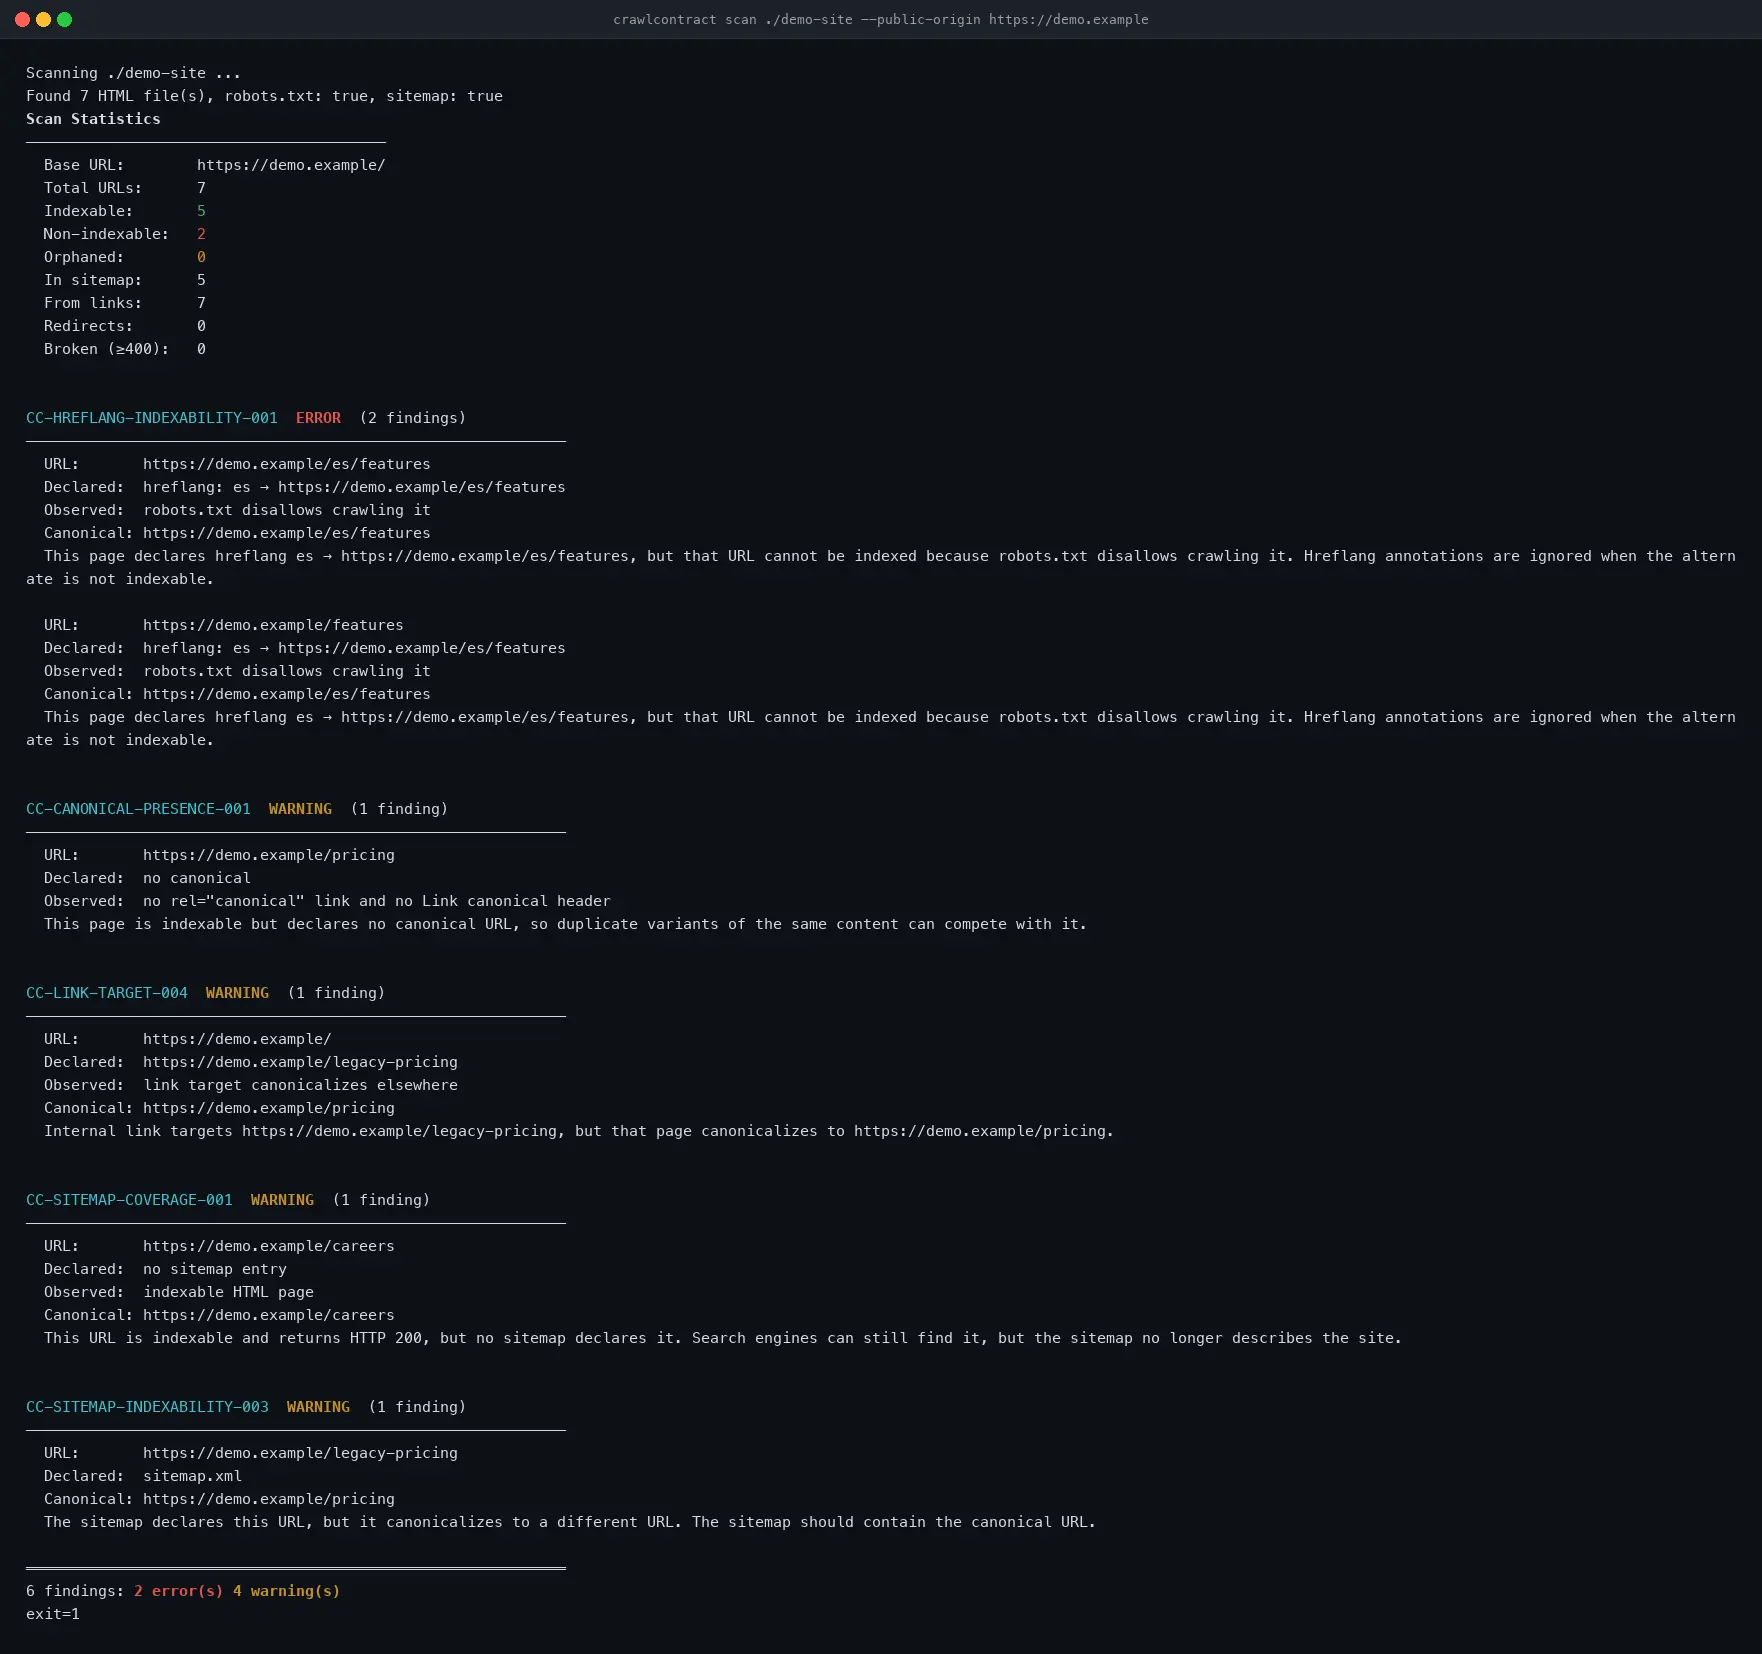
For a deployment check, it takes a sample of logged URLs and requests them from both the current site and your preview environment. It compares responses, redirects, canonical URLs and indexing directives, and flags changes to language links, structured-data types and page text.
The question is fairly simple: these URLs are already being requested—what happens to them after this change?
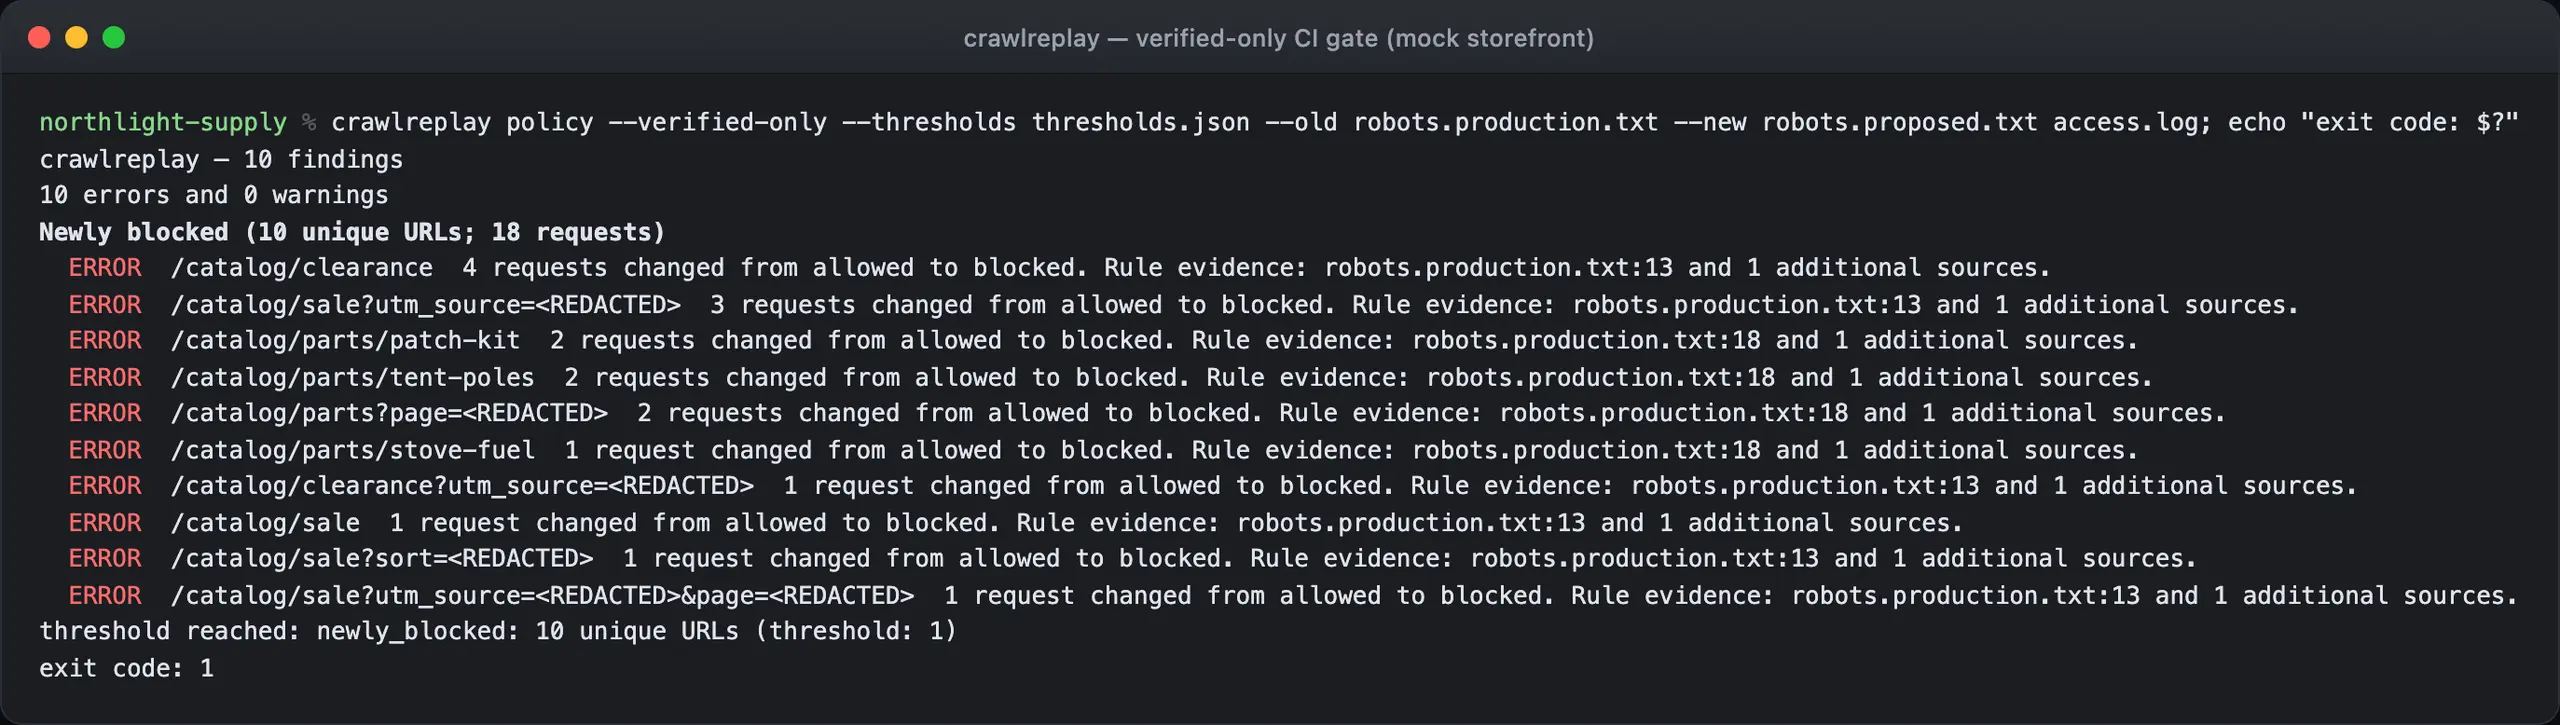
It works with Nginx and Cloudflare Logpush logs, with reports you can read locally or use in an automated workflow. You can set thresholds for newly blocked URLs, new noindex directives and worsening HTTP responses, so those findings can fail a check before a release goes ahead.
It’s written in Rust and is still in early development. The checks cover the logged URLs you feed it and the sample you choose for a deployment comparison, so the logs you use matter.